B6 rank-one SBC R2: exact same-dataset longer-budget NUTS refit
One repaired computational screen is not SBC or interval coverage
Research-only diagnosis of the same original stage-zero replicate 1. This is not a fresh prior-generated dataset and adds zero independent SBC replicates. Stable 1.1.0 and scientific/release qualification flags remain unchanged.
Original evidence
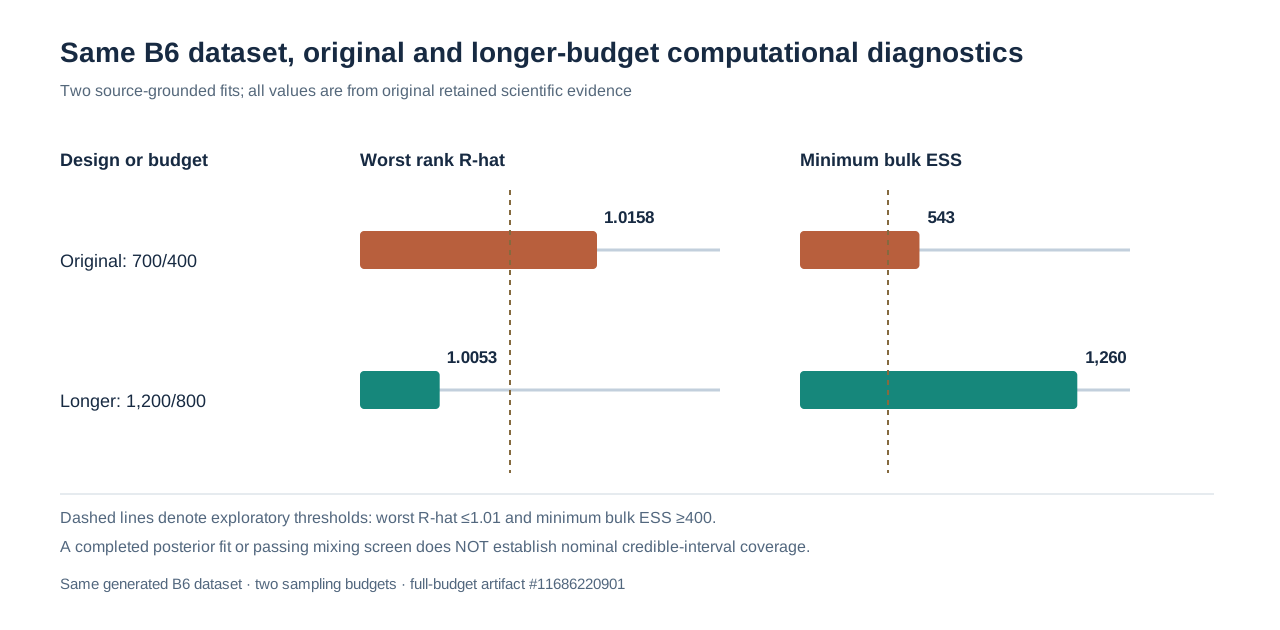
The first B6 prior-SBC stage-zero study used four chains with 700 warmup and 400 retained draws per chain. Its generating dataset replicate 1 missed the predeclared exploratory mixing screen (worst identified-functionals rank R-hat 1.0158, minimum bulk ESS approximately 543), despite zero divergences. A new, independent dataset was not generated to investigate this failure.
The targeted longer-budget refit is research draft PR #276, exact research SHA 91689b02bfcd9e1fc09cda6d77de62c2ed87bc77, scientific run #38095220518. The original 2/2 scientific jobs and its full 25/25 exact-head engineering CI passed. Original checksum-retained fit artifact 11686220901 includes case.json, reliability.json, evidence.json, and SHA256SUMS. Dataset seed was unchanged, 6900046115226145480; sampling initialization seed relationship, likelihood and priors were also retained.
| Diagnostic, identical generated dataset | Stage-zero pilot | Longer-budget R2 refit |
|---|---|---|
| Chains | 4 | 4 |
| Warmup per chain | 700 | 1,200 |
| Retained posterior draws per chain | 400 | 800 |
| Worst rank-normalized R-hat across six x population mean/variance functionals | 1.0158 | 1.00531249 |
| Minimum bulk ESS across six identified functionals | approximately 543 | 1,260.40 |
| Min energy BFMI in longer refit | Not repeated here | 0.847704 |
| Divergences | 0 | 0 |
| Predeclared all-functionals screen | Failed | Passed |
| Full refit wall time including compilation/tuning | Not compute-matched | 1,419.03 seconds (23.7 minutes) |
The computational screen checks all six identified functionals, not only the two primary midpoint SBC targets; threshold rank R-hat ≤1.01, bulk/tail ESS ≥400, energy BFMI ≥0.3 and zero divergences.
The original longer-refit midpoint mean truth rank was 1,829 of 3,200 draws, and midpoint variance truth rank 2,009 of 3,200. Their marginal 90% posterior intervals each included the same generating truths; this is only an observed outcome on one previously tested dataset, not repeat nominal coverage or a valid additional SBC rank in the four-dataset histogram.
Scientific interpretation and reliability denominators
The evidence shows that the shorter sampling budget was a plausible cause of this one computational-screen failure: when sampling was extended on the identical dataset, the worst R-hat fell below the exploratory ceiling and all six population functionals passed. It cannot establish that longer chains will fix nonconvergence systematically or that the posterior uncertainty is calibrated.
The reliability.json record keeps computational reliability (all attempted datasets passing diagnostics), conditional interval inclusion (only among adequately sampled datasets), and end-to-end screen-and-interval success (over all attempts) separate. This targeted refit contributes only one repeated computation on an existing dataset to those diagnostic denominators. The uncorrected pilot failure remains preserved in the original four-dataset record. Do not retroactively turn its stage-zero screen-pass rate of 3/4 into 4/4 by substituting the longer refit.
Next: a separate independently seeded study with prespecified sampling budgets and Monte Carlo error targets, including all fit exceptions and screen failures. Scientific blocker #255 remains open; rank-based SBC uniformity, nominal interval coverage, fixed-parameter repeated coverage and release readiness are not established.