Participant-held-out validation
A validation split is part of the scientific claim, not merely a machine-learning implementation detail.
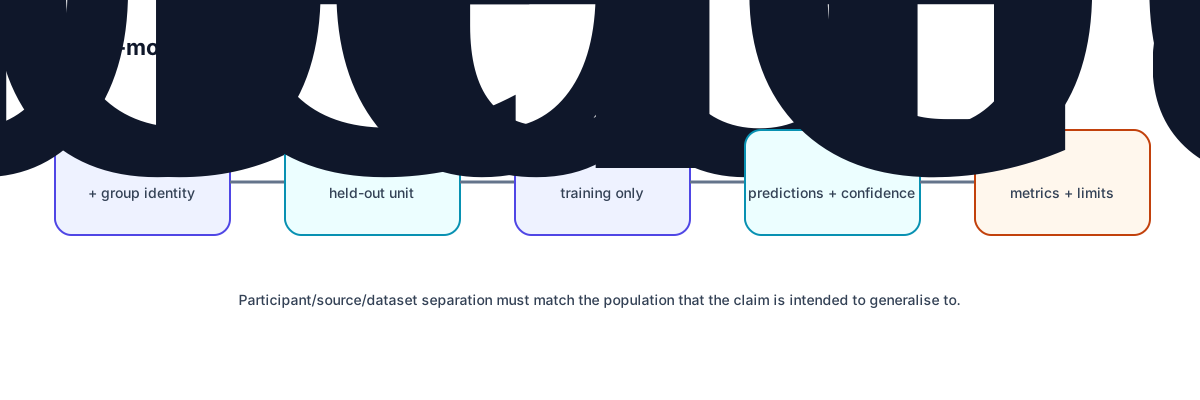
Match the held-out unit to the claim
If a model is expected to work for new participants, samples from the same participant should not appear in both training and evaluation solely because they occur at different timestamps or trials.
The corresponding principle applies to source files, studies, datasets, devices, and stimuli: the held-out identity should match the intended generalisation boundary.
Report more than one headline score
For event models, include the grouping design, class support, calibration where relevant, event-level performance, sample-level performance when scientifically useful, and the reference-label provenance.
Avoid claim promotion
Good held-out performance on one public dataset does not establish native-device validity, cross-dataset robustness, or construct validity.